Nightly
No. 79Wednesday, 30 September 20264 min read

You’re reading an archived edition. Today’s is here →

Good morning.

OpenAI just slashed token prices again, and the math feels like a cheat code.

AI pricing

GPT-6.1 Sol costs a fifth of Astra

Token price shock: GPT-6.1 Sol offers near‑Astra coding ability while charging only one‑fifth the input and output token price of Astra. The lower cost could make high‑end LLM use affordable for more teams.

Why it mattersCheaper tokens let you run more inference cycles without blowing your cloud bill.

Benchmarking

UserProxyBench reveals 15‑point reward swing

User fidelity matters: Swapping user simulators across 375 enterprise tasks changes mean task reward by 15.2 points, and 24.4% of successful runs break user specs. The new User Fidelity Score quantifies that drift.

Why it mattersUnderstanding proxy quality helps you trust agent evaluations before deployment.

LLM serving

SPLASH enables live attention layout swaps

No downtime serving: SPLASH lets a running LLM switch its parallel attention layout on the fly, avoiding worker drains and restarts. It keeps requests flowing while the backend reconfigures.

Why it mattersZero‑downtime layout changes mean higher throughput for your inference fleet.

Quick hits

That’s your two‑minute sprint. Catch you tomorrow

9 stories
Top pickResearcharXiv cs.AI

UserProxyBench adds a User Fidelity Score and shows that swapping the user proxy across 375 enterprise tasks shifts mean task reward by 15.2 points, with 24.4% of successful episodes violating user specifications.

  • 15.2 point reward change
  • 24.4% violations
  • 375 tasks

The benchmark sits on top of the tau-bench family and evaluates the simulated user independently of agent success. The most common error is premature disclosure, where the user reveals information before being asked. This highlights the need for better user modeling in agent evaluations.

arxiv.org
Top pickResearcharXiv cs.AI

The paper proposes agentic meta-reasoning, an inference-time controller that makes stepwise execution choices explicit and keeps only a compact run summary instead of replaying full history.

The system separates workers that perform task-level computation from a controller that consolidates progress, explores options, assesses budget impact, and dispatches work with context from persistent memory. Baselines include production coding agents and a Direct Control Agent using the same resources.

arxiv.org
Top pickResearcharXiv cs.CL

LongHarness Bench introduces a benchmark to assess both effectiveness and efficiency of long-context language model harnesses using diverse retrieval and adaptive reasoning tasks.

Current long-context evaluations show saturated accuracy, making it hard to differentiate harnesses. The new benchmark requires lexical and semantic search, and only a small subset of the large context is useful at each step, creating varied accuracy‑cost trade‑offs.

arxiv.org
Newsopenai blog

OpenAI DevDay 2026 announced more than 20 new features, including GPT-6 Astra, updates to ChatGPT and Codex, new APIs, security enhancements, and builder tools.

  • 20+ announcements

The announcements span improvements in model capabilities, developer access, and safety measures, aiming to broaden the ecosystem for both consumer and enterprise applications. Specific product roadmaps were outlined for upcoming releases.

Releaseopenai blog

GPT-6.1 Sol delivers near‑Astra coding and professional work intelligence at one‑fifth the standard API input and output token prices of Astra.

  • 1/5 token price

Positioned as a cost‑effective alternative, Sol targets developers needing high‑quality code generation and computer‑use assistance while reducing operational expenses. It retains most of Astra’s performance characteristics for coding tasks.

Researchhuggingface blog

The article presents source‑aware verification techniques for MCP agents to ensure generated facts are backed by correct sources.

It outlines methods for integrating source checking into agent pipelines, improving reliability of multi‑chain processing (MCP) agents. The approach aims to reduce hallucinations by tying each claim to verifiable evidence.

Researchhuggingface blog

NVIDIA Kumo Tabular is a new model for tabular prediction that claims higher accuracy while using less compute than prior approaches.

The model targets common tabular benchmarks and is positioned as a frontier in the accuracy‑efficiency trade‑off, aiming to reduce inference cost for production workloads.

RepoHF trending302 likes

SupersonicLabs/Julia-1 is a text‑classification model on Hugging Face with 1,725 downloads and 302 likes.

  • 1,725 downloads
  • 302 likes

The model is listed under the HF trending section and is intended for general text classification tasks, showing modest community interest.

RepoHF trending268 likes

apple/LensVLM-9B is an image‑text‑to‑text model on Hugging Face with 1,956 downloads and 268 likes.

  • 1,956 downloads
  • 268 likes

LensVLM-9B combines visual and language capabilities, targeting multimodal generation scenarios, and has attracted a moderate number of users on the platform.

6 stories
Newslwn

Andres Freund discussed PostgreSQL performance and kernel interactions at the 2026 Kernel Recipes conference.

  • 2026 Kernel Recipes

Freund highlighted how Linux kernel features affect database workloads and suggested improvements to better support PostgreSQL, referencing recent developments in both projects.

lwn.net
Newslwn

Security updates were released Tuesday for multiple Linux distributions, covering dozens of packages.

Distributions including AlmaLinux, Debian, Fedora, Mageia, Slackware, SUSE, and Ubuntu published patches for components such as kernels, libraries, and server software to address recent vulnerabilities.

lwn.net
Releaselwn

Firefox version 157.0 was released, adding a visual refresh and hardware AV1 decoding for WebRTC.

  • Version 157.0

The update also includes numerous bug fixes and performance improvements, marking the most significant UI overhaul in years while enhancing media handling capabilities.

lwn.net
Releaselwn

Rust GPU maintainer Christian Legnitto showcased a prototype aiming to make GPUs a native compiler target for standard Rust code, eliminating the need for special libraries.

The prototype builds on rust-gpu and Rust CUDA but extends them to support ordinary Rust without additional ecosystem layers. Legnitto presented this vision at RustConf 2026, indicating future work toward full implementation and release. The approach could simplify GPU programming in Rust by leveraging existing compiler infrastructure.

lwn.net
hackaday

Lithium batteries have become the backbone of many modern devices ranging from toothbrushes to semi trucks, so what are we going to do with them when these rechargeable cells finally …read more

hackaday

Even if almost tragically impractical in a world where digital calculators are cheap as chips, mechanical calculators and their big mechanical computer brethren remain an absolute marvel of engineering. Using …read more

6 stories
Top pickarXiv cs.DC

Asynchronous Byzantine Reliable Broadcast (BRB) is a fundamental primitive that guarantees agreement and validity in distributed systems subject to Byzantine faults, but it lacks ordering guarantees. Causal message order…

Asynchronous Byzantine Reliable Broadcast (BRB) is a fundamental primitive that guarantees agreement and validity in distributed systems subject to Byzantine faults, but it lacks ordering guarantees. Causal message ordering is important for many applications such as blockchain and social networking. Existing solutions for Byzantine Causal Reliable Broadcast (BCRB) have several drawbacks. Such protocols typically append vector clocks or dependency barriers to application messages, resulting in a metadata overhead that scales linearly with $n$, the number of processes in the system. In this pape…

arxiv.org
Top pickarXiv cs.CR

We present an efficient linkage-based model for in-process compartmentalization built on CHERI memory safety, which enables fine-grained compartmentalization of the entire UNIX user-space, scaling to 10K+ compartments on…

We present an efficient linkage-based model for in-process compartmentalization built on CHERI memory safety, which enables fine-grained compartmentalization of the entire UNIX user-space, scaling to 10K+ compartments on desktop systems. The model's "push-button" compartmentalization along existing library boundaries regularly hosts 500+ compartments per process for large applications such as Chromium, far exceeding the number of concurrently available protection domains supported by other mechanisms (e.g., up to 16 for Intel MPK). Custom policies can further subdivide libraries. Of the thousa…

arxiv.org
arXiv cs.DC

Production machine learning (ML) stacks often split graph compilation and kernel execution across different layers and languages, making backend behavior, deployment guarantees, and performance fallbacks hard to reason a…

Production machine learning (ML) stacks often split graph compilation and kernel execution across different layers and languages, making backend behavior, deployment guarantees, and performance fallbacks hard to reason about end-to-end. RLX addresses this gap with a single Rust codebase that combines compiler and runtime roles around one primitive-level, three-level intermediate representation (IR), plus a transparent dispatch contract that resolves each operator to native, common-IR, or rewritten lowering and fails compilation when legalization is not possible. The same IR targets fourteen ru…

arxiv.org
ResearcharXiv cs.DC

SPLASH is a serving system that can switch the parallel layout of attention for large language models while requests are running, avoiding the need to drain and restart workers.

The system leverages the decoupling of KV cache location from attention weight sharding in modern attention implementations, allowing seamless handoff between tensor, data, and context parallelism as workload characteristics change.

arxiv.org
ResearcharXiv cs.LO

The authors introduce a translation framework from Bach to mCRL2 to enable model‑checking of shared‑space coordination programs with richer temporal specifications.

Existing tools like Anemone only support reachability checks; the new framework aims to verify liveness and invariants such as "every request is matched by a response" and "no message is silently lost", extending verification beyond state attainability.

arxiv.org
ResearcharXiv cs.DC

DScale improves block‑diffusion speculative decoding by adding a lightweight 112K‑parameter predictor and adaptive verification that halves verification padding on A100‑40GB GPUs.

  • 112K‑parameter predictor
  • A100‑40GB GPU
  • concurrency 8‑32

The approach keeps the original drafter architecture and full draft length, using path‑aware tiles and dynamic verify‑length allocation to reuse captured graphs and reduce rejected candidates, showing gains on Qwen3‑8B and Qwen3‑4B across four datasets.

arxiv.org
6 stories
RepoGitHub trending · rust9,394 ★

The ccfddl/ccf-deadlines repository provides an agentic tracker for CCF‑ranked and worldwide conference deadlines via website, Python CLI, and WeChat applet.

It consolidates deadline information in a single source, enabling developers and researchers to stay up‑to‑date on submission windows without manually checking multiple sites.

RepoGitHub trending · python1,790 ★

SemiAnalysisAI/InferenceX is an open‑source platform that standardizes inference research workflows for Python projects.

The repository offers modular components for model loading, benchmarking, and deployment, aiming to reduce duplication of effort across academic and industry inference experiments.

RepoGitHub trending37,707 ★

VectifyAI/PageIndex is a document‑indexing tool designed for vectorless, reasoning‑based retrieval‑augmented generation.

By avoiding dense vector embeddings, PageIndex focuses on symbolic reasoning to match passages, supporting use cases where interpretability and logical consistency are prioritized over pure similarity search.

RepoGitHub trending · python83,257 ★

bytedance/deer-flow is an open-source long‑horizon SuperAgent framework that coordinates sandboxes, memory, tools, subagents and a message gateway to tackle tasks ranging from minutes to hours.

The system is designed to research, code, and create autonomously, integrating multiple skill modules. It aims to handle complex, multi‑step workflows without human intervention, extending prior agent‑oriented architectures.

RepoGitHub trending3,246 ★

cs341-illinois/coursebook is an open-source introductory systems programming textbook used for the University of Illinois CS341 course.

The repository provides lecture notes, assignments, and examples covering low‑level programming concepts. It is intended as a free alternative to commercial textbooks and is continuously updated by the course staff.

RepoGitHub trending49,273 ★

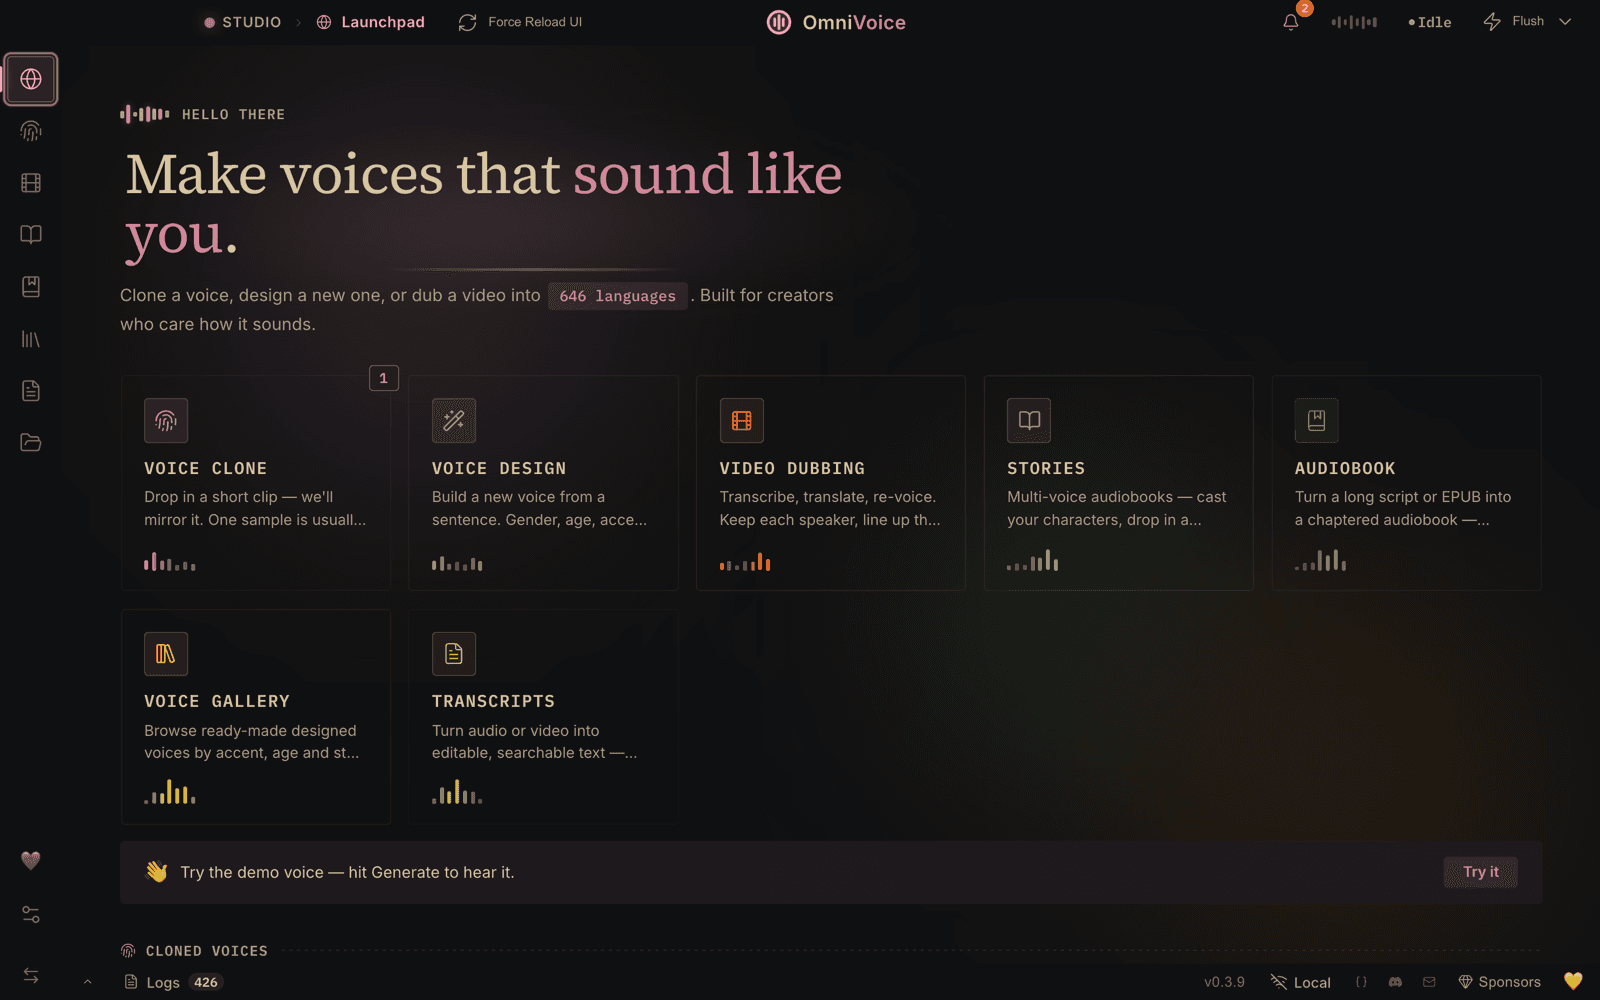
debpalash/VoiceStudio is an open-source, fully‑local alternative to ElevenLabs offering voice cloning, design, dubbing, dictation, transcription and audiobook generation in 646 languages.

  • 646 languages supported

All processing runs on the user's hardware, eliminating cloud‑based privacy concerns. The toolkit includes models for both speech synthesis and recognition, enabling end‑to‑end audio workflows without external services.

You’re all caught up.

27 stories from 209 scanned overnight.

archived edition · 209 fetched → 27 publishedj/k move · enter expand · o open · / search